Home / Deep web surface web dark web
Deep web surface web dark web
This guide is for beginners looking to understand the web layers and their implications for everyday users and small businesses.
The surface web is public content indexed by traditional search engines[1]. The deep web covers unindexed content, such as private email, banking dashboards, databases, and login-protected pages[1][2], while the dark web is a smaller deep-web subset built to conceal identities and requiring special software, configuration, or authorization[1].
The Web as an Iceberg: A Useful Analogy With Limits
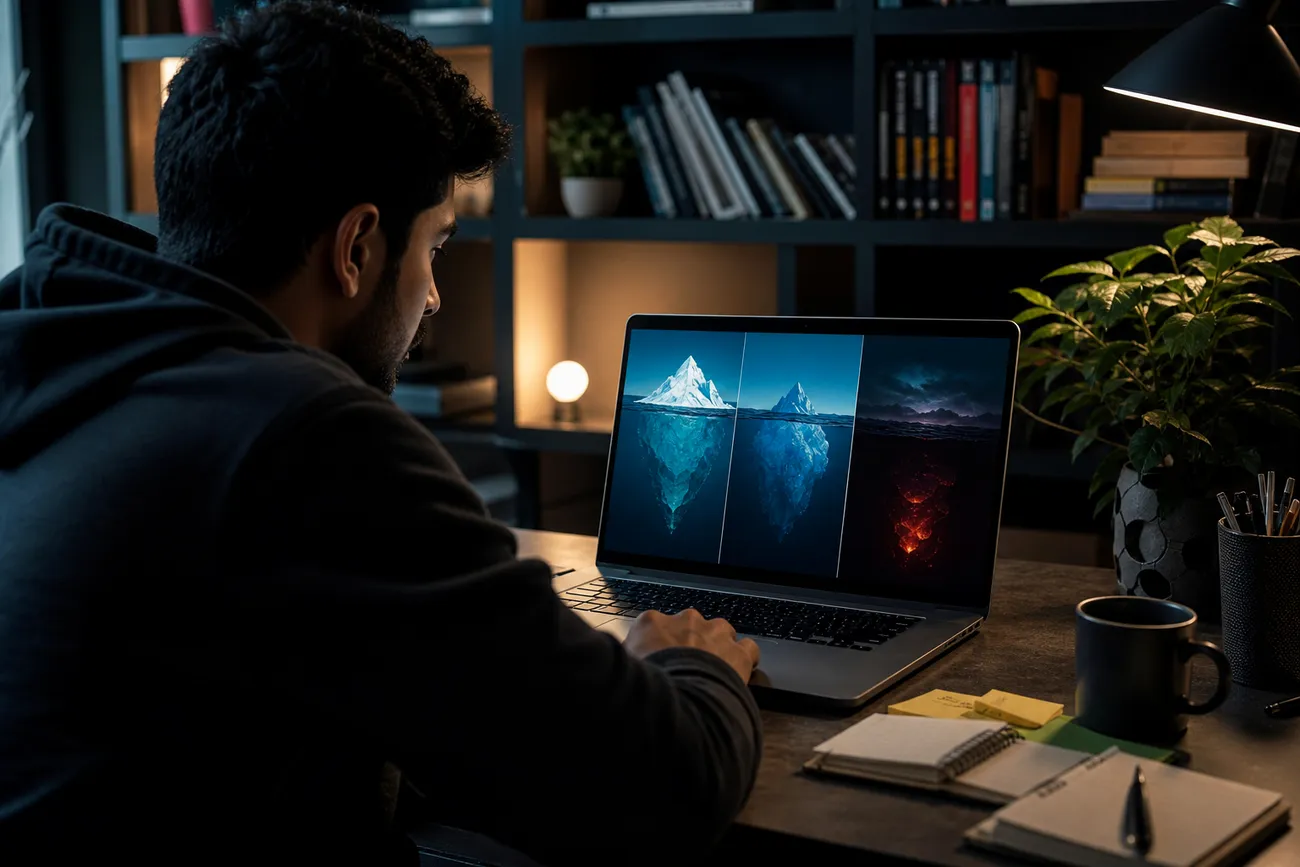
Visualizing the web as an iceberg provides a helpful perspective on its structure. Above the waterline lies the surface web, which includes all the publicly accessible content indexed by search engines. This portion is familiar to most users and consists of sites like news outlets, e-commerce platforms, and social networks. However, the bulk of the iceberg, submerged beneath the surface, represents the deep web — an extensive area of unindexed content that includes databases, private forums, and login-protected sites[3][1].
It’s important to understand that these layers are not equal in size or function. The deep web is significantly larger than the surface web, but quantifying its exact size is challenging. The Congressional Research Service notes that reliable metrics for the deep web's scale are lacking, and estimates often vary widely[3]. This uncertainty means that while the iceberg analogy is visually appealing, it oversimplifies the complexities of online content.
The dark web, often confused with the deep web, is a specific subset that requires special software, such as the Tor Browser, for access. This layer is designed to enhance user privacy and anonymity, hosting various services that are not indexed by traditional search engines. However, it should be noted that the dark web is just a small part of the deep web and not representative of its entirety[1].
For those curious about what lies beneath the surface, exploring the deep web can reveal valuable resources, but it’s essential to approach it with caution. Engaging with this layer of the internet involves navigating both legitimate and potentially harmful content, making awareness and understanding crucial.
Surface Web vs. Deep Web vs. Dark Web at a Glance
A clear comparison between the surface web, deep web, and dark web highlights their distinct characteristics. Each layer serves different purposes and has unique access requirements, content types, and levels of anonymity.
| Feature | Surface Web | Deep Web | Dark Web |
|---|---|---|---|
| Search Engine Indexing | Indexed by traditional search engines[1] | Not indexed by traditional search engines[1] | Requires special software for access[1] |
| Access Requirements | No authentication needed | Authentication or paywall may be required[2] | Requires Tor Browser or similar tools[1] |
| Typical Content | Public company pages, blogs, news sites | Private email inboxes, databases[2] | Onion services, illicit markets[1] |
| Anonymity | Low; user data is often tracked | Moderate; some content is private but traceable | High; designed to conceal user identity[1] |
| Common Tools | Web browsers (Chrome, Firefox) | Standard browsers with login credentials | Tor Browser, VPNs |
| Relative Risk | Generally low, but phishing exists | Moderate; depends on site security | High; potential exposure to illegal activities[4] |
For example, a public company page illustrates surface web content, easily accessible and indexed by search engines. In contrast, a password-protected email inbox represents deep web content, requiring authentication for access. Lastly, a Tor-based onion service, accessible only through the Tor network, exemplifies the dark web, emphasizing anonymity and privacy.
Understanding these layers is crucial, especially since the dark web is a part of the deep web and not a separate entity. Users should approach each layer with awareness of its specific risks and benefits.
What Is the Surface Web?
The surface web refers to content that is publicly accessible and indexed by traditional search engines. This layer includes a variety of websites, such as news sites, public blogs, product pages, and even small-business websites that have been optimized for search engine visibility. While many users interact with this content daily, it is crucial to understand that not every public page is indexed, and some may still be difficult to find despite being accessible[1].
Search engines utilize web crawlers to navigate the internet, following links to discover and index new content. Crawlers systematically visit web pages, collect information, and store it in vast databases that power search results. For example, a local bakery's website may appear in search results if it has been indexed, allowing potential customers to find it easily. However, if the bakery's website is not properly optimized or linked to other indexed pages, it might remain hidden from search results despite being publicly accessible.
The surface web is often likened to the tip of an iceberg, representing only a fraction of the total online content. While it contains valuable information, the deep web, which includes unindexed material like databases and password-protected sites, comprises a much larger portion of the internet[3]. Although the surface web is more visible, it is essential to recognize that a significant amount of information lies beneath its surface.
In summary, the surface web is the layer of the internet that most users are familiar with. It is characterized by publicly accessible content that search engines can discover and index, making it easy for users to find information on various topics.
What Is the Deep Web?
The deep web is primarily composed of content that remains hidden from traditional search engines due to various access requirements. This includes ordinary online activities such as online banking, webmail, cloud storage, medical portals, and subscription-based content. Unlike the dark web, which often evokes images of illicit activities, the deep web mainly consists of legitimate, everyday resources that require authentication, forms, or paywalls to access[1].
For instance, when a user logs into their online banking account, they are accessing deep web content. This information is not indexed by search engines, as it requires a username and password for entry[2]. Similarly, medical records stored in online portals or a company’s customer relationship management (CRM) system are also part of the deep web. These platforms are designed to protect user privacy, ensuring that sensitive data is not accessible to the general public.
Many people interact with the deep web on a daily basis without realizing it. Activities like checking personal emails, accessing cloud storage services, or viewing subscription-based articles all take place within this layer of the internet. In fact, it is estimated that the deep web is significantly larger than the surface web, although quantifying its exact size is challenging[3].
Understanding the deep web is crucial for recognizing how much of the internet users engage with daily. While the vast majority of this content is benign and necessary for various online activities, it is essential to approach it with an awareness of security measures, such as using strong passwords and enabling multi-factor authentication, to protect personal information.
What Is the Dark Web?
The dark web is a part of the deep web that is intentionally concealed and requires specific software or configurations to access, with Tor being the most common tool. This layer of the internet is designed to enhance privacy and anonymity for its users, allowing them to communicate and exchange information without revealing their identities. Accessing the dark web typically involves using .onion addresses, which are unique URLs that can only be reached through the Tor network. These addresses consist of 56 characters followed by .onion, ensuring that the services are not indexed by traditional search engines and remain hidden from the public eye[5].
Onion services, a key feature of the dark web, facilitate encrypted communication between users and servers. Unlike standard web traffic, which can expose a user's IP address, traffic to onion services remains encrypted end-to-end, enhancing user privacy[6]. While the dark web is often associated with illicit activities, it also hosts legitimate services that prioritize privacy. For instance, the CIA launched its official Tor site in 2019 to provide secure access to information without the risk of impersonation[7].
However, the dark web is not without its dangers. It is home to various scams and criminal marketplaces, making it essential for users to exercise caution. Law enforcement agencies have successfully identified numerous dark-web operators and users, as demonstrated by operations that have shut down hundreds of thousands of fraudulent sites[4].
In summary, while the dark web offers legitimate privacy-focused communication options, it is also a space where scams and illegal activities thrive. Users should approach this layer of the internet with a clear understanding of its risks and benefits, recognizing the need for awareness and caution when navigating its unique landscape.
How Indexing, Access, and Anonymity Actually Differ
The terms "not indexed," "password-protected," and "anonymous" describe distinct properties of web content and should not be treated as synonyms. Understanding these differences is crucial for navigating the complexities of the internet.
Indexing and Access
Search engine indexing refers to the process by which web crawlers discover and catalog content. The surface web consists of pages indexed by traditional search engines, making them easily accessible[1]. In contrast, the deep web contains content that is not indexed, such as databases and login-protected sites[1]. This means that while a public webpage may be visible to anyone, a password-protected email inbox is only accessible to authenticated users and remains hidden from search engines[2].
On the other hand, the dark web is a subset of the deep web, requiring special software, like the Tor Browser, for access. This layer is specifically designed to conceal users' identities and is not indexed by search engines[1]. Accessing dark web content involves navigating through .onion addresses, which are accessible only via the Tor network and are encrypted to protect user privacy[5].
Anonymity
Anonymity on the internet varies significantly across these layers. The surface web typically offers low anonymity, as user data is often tracked and collected. The deep web provides moderate anonymity, as some content is private but can still be traced back to users, especially if proper security measures are not taken. In contrast, the dark web emphasizes high anonymity, designed to conceal users' identities through Tor routing, which encrypts traffic end-to-end between the client and the onion service[6].
Classification Scenarios
To clarify these distinctions, consider the following scenarios:
Unindexed Public Page: A website that is not linked to other pages and therefore remains undiscovered by search engines. Although publicly accessible, its lack of indexing makes it hard to find without direct knowledge of the URL.
Private Customer Portal: A login-protected site where users must authenticate to access their accounts. This deep web content is essential for secure transactions but is not visible to search engines[2].
Tor Onion Service: A service accessible only through the Tor network, characterized by its .onion address. This dark web content is designed for anonymity and privacy, making it difficult for anyone outside the network to trace users[1].
Recognizing these differences can help users navigate the internet more effectively, ensuring they understand the risks and benefits associated with each layer.
Common Risks, Misconceptions, and Practical Safety Steps
Many misconceptions exist about the deep web and dark web. A common belief is that the deep web is inherently dangerous; however, it primarily contains benign content requiring authentication, such as online banking and subscription services[1]. Similarly, Tor, often associated with the dark web, is simply a tool for accessing both the deep web and dark web. It does not guarantee anonymity, as vulnerabilities exist that could expose users' identities[8].
Several risks are prevalent across these layers of the internet. Phishing attacks remain a significant threat, with cybercriminals often using fake links to steal credentials. Malware can be inadvertently downloaded from compromised sites, leading to data breaches. Additionally, businesses may face risks related to credential theft, especially if accounts are exposed on dark web forums. For instance, a business account with compromised credentials could be sold on the dark web, putting sensitive data at risk[9].
To navigate these threats effectively, consider the following checklist for enhancing online security:
- Use Unique Passwords: Avoid reusing passwords across different accounts to minimize risk.
- Implement a Password Manager: This tool can help generate and store complex passwords securely.
- Enable Multi-Factor Authentication (MFA): Adding an extra layer of security can significantly reduce the chance of unauthorized access.
- Keep Software Updated: Regular updates help protect against vulnerabilities that could be exploited by attackers.
- Control Access: Limit user access to sensitive information within an organization to reduce potential exposure.
- Interpret Dark-Web Monitoring Alerts Cautiously: While monitoring services can provide alerts for compromised credentials, they should be viewed as a detection measure rather than complete protection[9].
Understanding these risks and implementing practical safety steps can help users navigate the complexities of the deep and dark web with greater confidence.
Frequently Asked Questions
Many readers wonder whether ordinary use of the deep web requires special software. The answer is no; accessing deep web content, such as banking sites or subscription services, typically just requires standard web browsers and proper authentication credentials. However, to access the dark web, users must use specialized software like the Tor Browser, which allows them to navigate .onion addresses that are not indexed by traditional search engines[1].
Another common question is whether Google can index private content. Google cannot crawl pages that require a login, such as email inboxes or online banking dashboards, meaning this content remains hidden from search engine indexing[2]. This distinction highlights the difference between the surface web and deep web, where the latter contains a wealth of information that is inaccessible without proper authentication.
Legality is a crucial aspect to consider. While accessing the Tor network and using the Tor Browser is legal in most countries, any illegal activities conducted through these platforms are still subject to local laws[10]. Investigators have developed methods to identify dark web users, often through operational mistakes, compromised services, or traditional investigative techniques. For instance, law enforcement agencies have successfully shut down numerous dark web sites and identified their operators through operations like Operation Alice, which led to the shutdown of over 373,000 fraudulent sites[4].
Some notable dark web sites serve legitimate purposes. For example, the CIA operates an official onion service to provide secure access to information, allowing users to avoid scams and impersonation[7]. This emphasizes that while the dark web often carries a negative reputation, it also hosts legitimate resources alongside illicit activities. Understanding these facets can help users navigate the complexities of the deep web and dark web more effectively.
Things readers ask
- Is the dark web part of the deep web?
Yes. The dark web is a subset of the deep web built on overlay networks that require special software, configuration, or authorization[1]. Most deep-web content is far less dramatic: login pages, databases, unlinked pages, and non-indexable forums also belong there[1].
- Is entering the dark web illegal?
Usually, no. The Tor Project says downloading Tor Browser and using Tor is legal in nearly every country, but crimes committed through it remain illegal[10]. Local restrictions can differ, so the reader should check applicable law before connecting.
- Can the FBI track the dark web?
Dark-web users are not automatically untraceable. Tor cannot guarantee perfect anonymity, and torrent software or externally opened documents can expose a real IP address[8]. Europol reported that an operation conducted from March 9–19, 2026 shut down more than 373,000 fraudulent sites and identified 440 customers, demonstrating that law enforcement can uncover users and operators[4].
- What are the top 5 dark web sites?
There is no dependable “top five” because onion services frequently disappear, duplicate content, or change addresses. A 2025 study examining more than 25,000 Tor sites estimated that approximately 82% of analyzed content was replicated[11]. Before trusting any directory, verify addresses through the publisher’s public website; older 16-character onion addresses no longer work[5].
- Can Google access the deep web?
Google cannot crawl private pages that require a login, including email inboxes and banking dashboards[2]. However, “blocked from crawling” does not always mean invisible: a URL disallowed through robots.txt may still appear in results when other pages link to it[12]. Sensitive material should therefore be password-protected or removed, not merely hidden from crawlers[12].
- Does dark web monitoring protect a small business?
It helps with detection, not complete protection. CISA recommends considering credential monitoring alongside phishing-resistant MFA and identity-access controls[9]. If an alert identifies an exposed account, the business should reset its credentials, revoke active sessions, review access logs, and check whether the password was reused elsewhere.
Conclusions
Keep the distinction simple.
- Classify content by how it is found, what permissions it requires, and which network can reach it.
- Everyday account dashboards and private databases are deep-web content, not evidence of criminal activity[1].
- Treat unfamiliar links cautiously; verify the publisher, avoid unexpected downloads, and never enter reused credentials.
- Small businesses should secure accounts before considering monitoring: enable MFA, restrict access, and investigate exposure alerts promptly[9].
- Specialized access tools improve privacy but do not erase operational mistakes, malicious files, or legal responsibility[8].
For a practical next step, review Exploring Deep Web Services: What to Expect before visiting unfamiliar resources.
Works cited
- A Primer on DarkNet Marketplaces
- Google Search Technical Requirements
- Dark Web
- Global cybercrime crackdown: over 373 000 dark web sites shut down
- Onion services - Features - Tor Browser
- About Tor Browser - Getting started - Tor Browser
- CIA's Latest Layer: An Onion Site
- Tor Browser best practices - Security - Tor Browser
- #StopRansomware Guide
- Fixed extra copy of FAQ questions - Tor Project commits
- Snorkeling in dark waters: A longitudinal surface exploration of unique Tor Hidden Services
- Robots.txt Introduction and Guide
Explore More About the Web Layers
Dive deeper into the intricacies of the web with our resources.
Visit Our Resources Top Deep Web Resources: What to ExploreDiscover top deep web resources to explore safely and anonymously. Learn how to access valuable information without compromising your priva…
 Phone Numbers on the Dark Web: What You Should KnowDiscover the risks of phone numbers on the dark web and learn practical steps to protect your personal and business information.
 Dark Web Websites with Videos: What to ExploreDiscover dark web websites with videos, learn how to explore them safely, and understand the risks involved in accessing this hidden conten…
 Best browser for deep webDiscover the best browser for deep web access, ensuring privacy and security while exploring onion services safely.